Has anybody yet made a comparison for 'AI' writing assistants for LibreOfficeWriter?

So, in my spare time I sometimes write fanfiction. I have wondered for a time whether that a LLM writing assistant could be helpful in this.

For example, if writing a character who likes to use ‘sophisticated’ language in order to appear smart but if you have trouble finding many sesquipedalian words yourself, it would be helpful if you could select their dialogue and ask for suggested edits to make his dialogue more needlessly ‘sophisticated’. Or to make suggestions for descriptions of the environment, clothing, gestures, and facial descriptions if one thinks a scene could use more of those but cannot decide which ones. (Naturally, I will still check everything myself; as LLMs can sometimes output obvious nonsense.)

I suspect much more could be done using ‘Artificial Intelligence’. Based on what I have been told about ‘AI coding assistants’ I think it should be possible to have an ‘AI writing assistant’ that can do such things as:
Suppose you are writing a story with an Original Character detective which is a Sherlock Holmes expy; then you could give that program some old Sherlock Holmes story as context and ask it to (re)write that characters dialogue based on Sherlock Holmes’ dialogue.
Though, I don’t know if there is already an extension made which supports something like that.

I have noticed that there already exist multiple extensions*:
localwriter » Libreoffice Extensions
LangAI Assistant » Libreoffice Extensions
WriterAgent
Nelson MCP
Kyber AI Companion, Local AI Assistant for LibreOffice
LibreThinker: AI Copilot for LibreOffice Writer
(Note, as new users can apparently only include two links in a post I was forced to remove the other links to those extensions.)

  • The list is not exhaustive I had dropped a few I found because they did not appear capable of using local models.

I had tried looking for any comparison between them, listing their capacities and the pros and cons they have against each other, so I could decide which was the best for my use case.
However, I failed to find any such comparison.

So, is there anybody here who has tried multiple of them and could give me any recommendations?

If not maybe I will try a few of them, like LangAI Assistant, myself for a week or so each and afterwards post my experiences back here. That might be helpful to others with the same question.

Why do you ask here and not your favourite AI ?
:rofl:

1 Like

I would say “no”, as you don’t ask the right question.
.
The extensions only create a connection from your LibreOffice to an AI. So making it easier to copy your planned dialogue to the AI and results back in your text.
.
Your question will be more, what model of AI can do the task? Does the model already knew Conan Doyle and Sherlock Holmes? Will you need to train the AI/give examples yourself.
.
So start to find the right AI for your task. Check how much this will cost you. Then find, if there is a tool also doing the copy/paste for you. (Last step: Put that AI in the author-field of “your” book.)

2 Likes

@Wanderer +1 :joy:

Duh, because several quick searches on the internet had not revealed any comparison between them already having been written.
Thus I presumed that an AI would likely not have had enough relevant high-quality information in its training data to produce an answer of sufficient quality to be worth asking for it.

Though, I think a better question would be why that you bothered to comment here if you don’t have any genuine questions or anything constructive to say but only troll posting?

I had heard of ‘AI’ IDE extensions where it was possible to add both internal and external files as ‘context’ to questions and commands; so I wondered whether maybe one of the LibreOffice extensions also had something like that.

I was planning to use an open source model on my own desktop…

So, had I instead used a thesaurus to rewrite that character’s dialogue to sound more ‘detective-like’ or ‘sophisticated’ would you then have suggested I would have mentioned that thesaurus as a fellow author of my fanfic?

Usually not, as you need to do some own thinking and writers skill yourself. But what you described is not authorship, but what a good editor will do with your script before publishing:

.
But do as you like. Conan Doyle is dead long enough to be legally used for everything anybody likey.
.

Still the same: Find a model first, then you may try how to connect it to LibreOffice for more convenience.

Ehm, how thoroughly did you read my first post?
The use cases I had mentioned there were such thing as rewriting dialogue or adding extra descriptions of the environment, clothing, gestures, and facial expressions into already existing scenes.
Not making the plot, characters, or scenes from the ground up…

In fact, although I had not mentioned so of that I can at least understand you missed it, it has often been a joy to me to derail the original work’s plot, make up characters with ‘interesting’ opinions and ‘eccentric’ tastes in fashion and cuisine, or write 'purple prose’y descriptions of the environment. However, I often find myself with dialogue which I suspect sounds unnatural but know not how to fix* or scenes which I think could use some extra description outside the dialogue but then suffering from writer’s block when I attempt to decide which extra descriptions of the environment, clothing, gestures, and facial expressions should be added. I had hoped that an LLM extension might prove useful in such circumstances.

*I suspect a result of English not being my first language.


I hope next comments will actually be productive.

Hi! There are no comparisons of the various plugins. WriterAgent has far more features than most of the others except nelson-mcp :wink: However, the full list of custom things someone might want for long-form writing is huge (keeping track of when characters learn things, etc.) and I’ve not really focused on super detailed things yet but my plugin can easily handle many scenarios such as the one you mentioned, especially if you have a good LLM, so give it a shot and file issues on GitHub if you find them.

1 Like

Hi!

Hmm; looking at its page (WriterAgent » Libreoffice Extensions) that indeed appears correct.
How did I miss that when I had visited it the first time?
Anyway I will certainly give your extension a try when I find the time for it. Poorly enough I was too busy with other things until now.

Ah, yes when I had looked at it I also had the impression much could be done through such an ‘MPC server approach’, though I wondered whether it might be less ‘user-friendly’ than the other extensions.


On some side notes:
I recently found out that WritingTool’s AI capacities are larger than I had previously thought.. Even more choice overload I guess.

I remember I had forgotten to ask in my first post how those extensions function when it comes to ‘data privacy’. However, now I am thinking about it, as I plan to use local models that might not be an issue anyway.

Hmm, now I wonder whether that I should have also asked whether anybody had made a good comparison for LLMs that could be used as writing assistants.
As now I have started looking for models to run locally and there are so much I have now possibly even worse choice overload…
There are various blogs comparing models. However, just after I started downloading a model which I thought was suited based on its description and required RAM, I found out it was about two years old*; which made me wonder whether it might be hopelessly behind by now.
But, I guess I should just continue looking for hopefully good models I could try out myself.

* Weirdly enough that blog post, where that model was recommended for editing, itself was only a few weeks old…

Hi Writer,

Feel free to check out my extension and file any bugss or ideas on Github. I’ll see if WriterTool has any features worth adding beyond grammar checking and consider adding it.

In terms of models to use, it’s a hard decision. I’ve got an eval framework I’m working on you can see on my GitHub page but it focuses on larger models. I’ll maybe do a local / small models eval one day. In the meantime, lots of people like Nemotron and Qwen models.

Hi Keith,

Ereyesterday, I encountered something which very much looks like a bug to me. I had already wanted to tell you about that then; but it was getting very late after I had finished going through those log files.
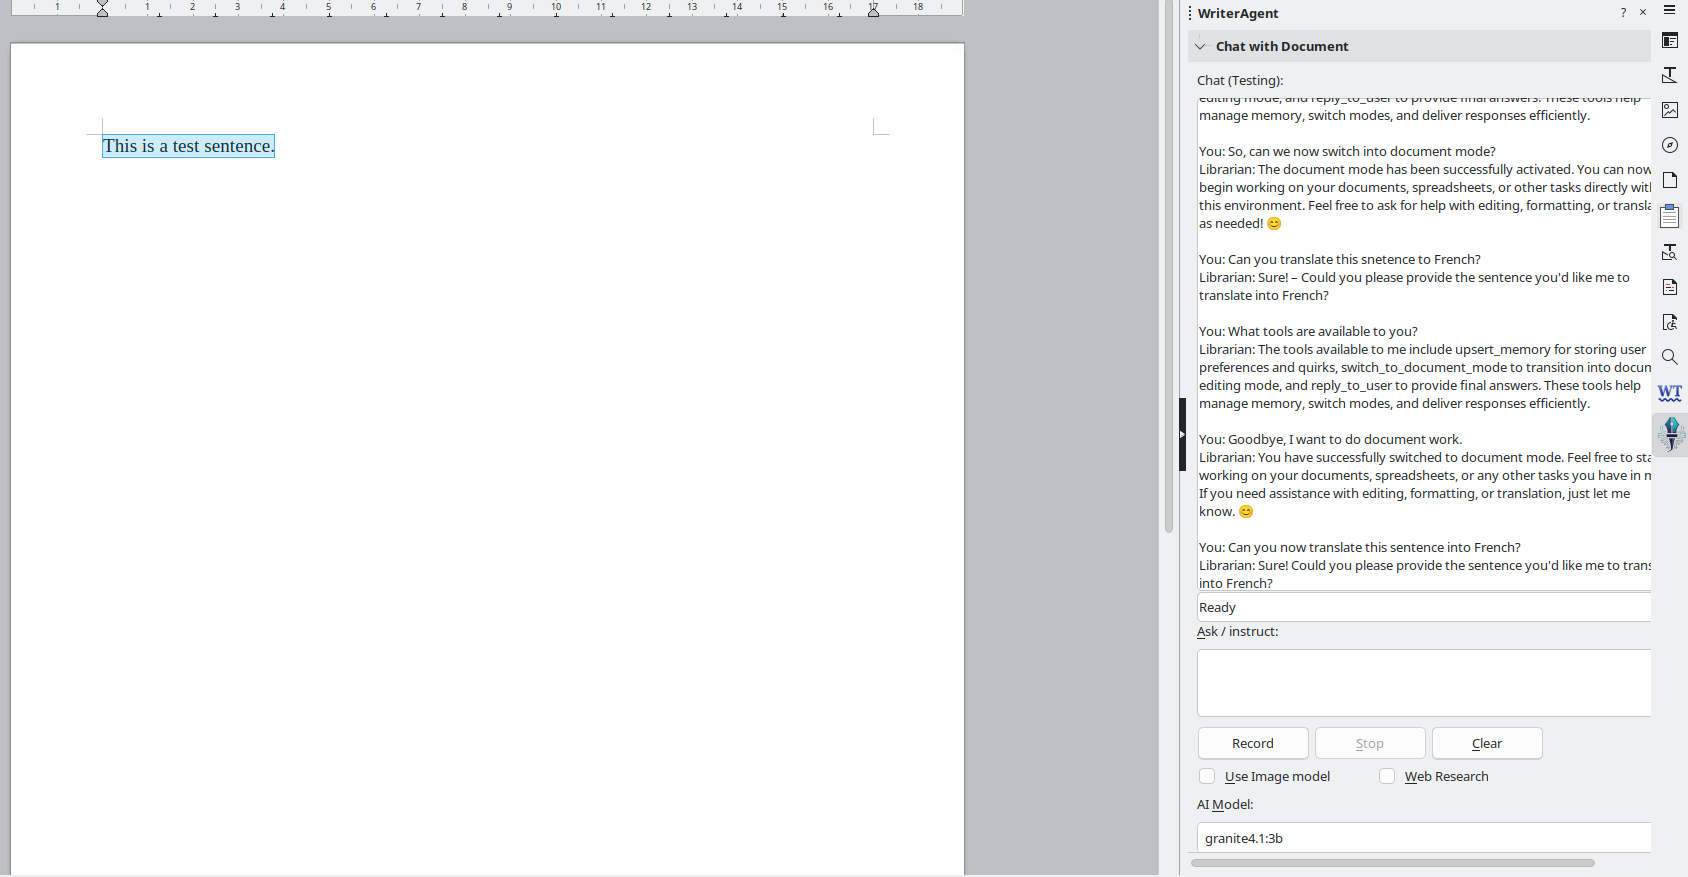
It appears that the sidebar chat can get stuck in the ‘Librarian onboarding flow’ with the tool ‘switch_to_document_mode’ doing nothing if ‘user.md’ was not yet filled in. The user is then not notified that the sidebar remains stuck in the ‘Librarian onboarding flow’ because no user preferences had been stored.

After trying out the ‘edit selection’ to see whether I had correctly connected WriterAgent with first LMStudio and then Ollama; I decided to try out the sidebar chat.
However, I ended up concluding that the model for some reason did not ‘see’ my document and was incapable of interacting with it; which seemed quite odd as your blog even had an example of the sidebar chat being used to translate a document.
When I went through the logs I discovered the existence of the ‘Librarian onboarding flow’* and decided to look up what it was by finding and skimming ‘librarian.py’ in the github repository. As it was not mentioned in readme.md or the description on extensions.libreoffice org, before this I had no idea such a thing existed.

However, when I attempted to get the sidebar to exit the ‘Librarian onboarding flow’ I discovered what very much looked like a bug to me:


When I later went through the logging I discovered that despite the model calling “switch_to_document_mode” it remained in the ‘Librarian onboarding flow’.
So, I once again went to look into your code in the Github repository; coincidentally I noticed that panel.py assigns ‘self._in_librarian_mode = True’ ‘if not user_md_exists’. So I concluded that it happened because it had not yet stored any of my ‘preferences’ in ‘user.md’.

Today, I had tried to first tell it a ‘favourite colour’ before attempting to switch to document mode, and it finally succeeded.
I got the sidebar chat to go over the first page and one by one provide feedback for the paragraphs there**.

As I do not think I am the only person whose reaction would be ‘I don’t see why my favourite colour is relevant, just start already’, I suspect that the ‘Librarian onboarding flow’ could be either better documented or reworked. On a sidenote, I think I myself would rather edit ‘preference settings’ myself rather than doing it via a chatbot; however, it could be I am the only one who thinks that so don’t take that as a suggestion.

If I find anything else I will post it on github; though, I’ll have to make a new account first, as I prefer to keep work and private accounts separate.

* Well, my actual reaction was more like: ‘so that was why that LLM kept asking me about my favourite colour, that was included in its instructions’…

** Even less of its ‘suggestions’ were ‘good’ than I had expected, it had even proposed I end a sentence with “…and escape routes for escaping.”. However, I haven’t yet had the time to try out different prompts and models; so I hope it eventually will get better.

It has the possibility to select single paragraphs and then through the right-click menu ‘ask AI’ such things as ‘add detected errors’, ‘revise paragraph stylistically’, ‘expand paragraph’, ‘find a synonym for this word’, ‘summarize’, or ‘translate’.
There also is a ‘general paragraph changes’ option which opens an ‘edit dialog’ which is a bit like your own ‘edit selection’ dialog but with more options and features.
Among others there is a seperate textbox displaying the ‘generated text’ complete with buttons such as ‘override paragraph’, ‘add to paragraph’, and ‘undo’; allowing the user more choice. A ‘temperature’ slider, a ‘select last paragraph’ button, and so on.

However, they work far from perfectly.
For example, when I had asked ‘Can you make the dialogue in this sentence appear more natural?’ the LLM had surrounded the text outputted in the ‘generated text’ field with:

Blockquote
Sure, here’s a more natural-sounding version of the dialogue:
—
<rewritten paragraph>
—

So that also gets placed in your text when click on ‘override paragraph’.

There also was an option to automatically ‘show suggestions for stylistic rewriting of paragraph in sidebar’. However, I did not yet found the time to test whether it even works in the first place.

I have also noticed that WritingTool appears to be incompatible with LM Studio.

I was planning anyway to test multiple models so I wonder whether I could maybe write something about which small local models I thought had worked best for me.
Though, I suppose that is something so context dependent people who aren’t fanfic writers who are writing in English despite that not being their first language might not learn much from that.
Thank you for the report. Yes, another user found it. I have the fixed version on GitHub, can you download that OXT and try it out? It has the same version number but that bug and a few other things are fixed. The one on the LibreOffice website I don’t update as frequently so i don’t upset them by posting builds multiple times per week :wink:

The results depend on the model you use. I mostly use high quality ones on OpenRouter, but feel free to let me know of any issues and I’ll look into it.

I’d love to get your advice on what small models work for you. I have an eval framework and I’m looking for test cases. Both to separate the small from the frontier models, but also among small models. But also I’d even put your suggestions in the readme since people don’t know what models to use. I don’t check here as often but let’s chat on GitHub…
upset
Regards,

-Keith

BTW, I put up a new version 0.7.7.3, which proper version numbers to make it clearer.It has a bunch of fixes over the version on the LO website. Please let me know how it goes, I’m curious to see what you and anyone else thinks of the real-time grammar checker. I’m actively developing it right now. It’s a sophisticated feature but it seems to be working fairly well now.

BTW, I changed the version so in the future it will tell you why it wants to know your favorite color, just to make it clearer. BTW, you can be as specific as you want. “Blue with red accent colors” Etc. It’s just something nice so that when it wants to add some color it knows what ones to use.

Ah, I had downloaded the .oxt from GitHub on 3 May, so it is quite the coincidence that was fixed just days after I had downloaded it.

Up till now I have only tried local models of a few GB. I have certainly noticed differences between them.

OK, I’ll make an account when I am finished with my preliminary comparison so we continue there.

Ah, I have just downloaded the update.

I think I can provide some suggestions when I am done testing multiple; I am not quite sure how good an attempt of me to rate models would be. However, even then it could still work as a list of suggestions for ‘models to try first’ for people suffering from overchoice.

Until now I have mostly tested three different models; I am trying out different workflows and then let Ollama/LM studio run when I do something else. I am not yet done, but I think I already found issues with all of them. Note, the following is only based on interacting with them in the sidebar, I did not yet found much time to test out the other functions:

1: granite4.1 3b: I think it is my least favourite model.
It seems to ‘hallucinate’ the most; first it had when reviewing paragraphs in the side bar included suggestions to improve a sentence I had never written and then assumed that character was from the US who based on the context was British.
Even when it comes to calling tools it seems to suffer from that problem; when I had asked it to edit the document to include its suggestions it instead changed the style of the entire document to ‘heading 2’.
Though, maybe it could be only a coincidence that most such ‘hallucinations’ have happened when working with that model?

2: mistral-nemo latest:
I have the impression this model is the best at the actual review work. However, it requires the most prompting to actually interact with the document; it even fails to notice the plain text ‘document context’ it receives as input together with the instructions and had to be explicitly told to use get_document_content before it started.
It also seems the slowest model; presumably because it is also the biggest I had downloaded.
It is also the oldest model, I think; maybe that is why it needs to prodded to interact with the document?

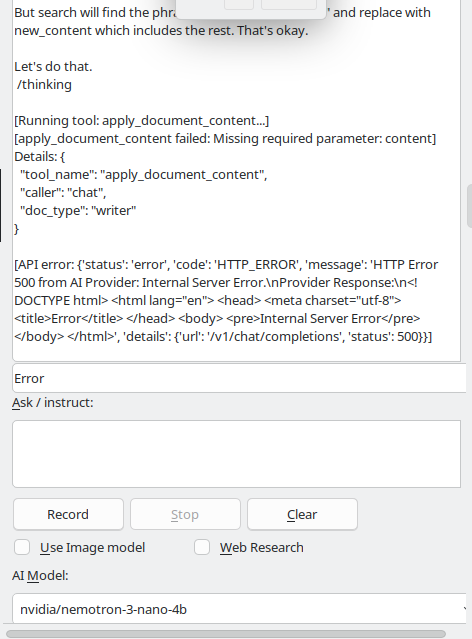
3: nvidia/nemotron-3-nano-4b:
This model seems to ‘think in circles’; one time it had placed a comment on the first paragraph and half an hour later it went back to it and then placed a second comment, worded differently but near identical in its meaning, right next to it.
It also seems very confused by the HTML tags in my LibreOffice document; did I unknowingly made a mess of that by pasting text from outside the document?
Once it had misread the ‘kinds’ as ‘kin ds’, I think because of HTML issues*, and then attempted to do something about that and decided to find the exact paragraph with the search function. This failed because ‘kin ds’ was not actually present in the document; a few steps later it would reattempt this.
Lastly, this model also seems to spend more time on thinking over how to proceed, on ‘understanding the document structure’, and also random issues like ‘why does document_stats give a different length in characters than document_length?’, than on reviewing the document or attempting to edit it.
Though, possibly some of that might be issues with my prompts. I think I’ll also check how much better nemotron-3-nano-4b works if I first nuke all formatting except for bold and italics**.
Finally, this model seemed to only notice it has access to functions as get_document_content or apply_document_content when I had explicitly told it that.

*Somewhere in the sidebar it had mentioned: Actually the HTML shows “<span style=“letter-spacing: normal”><span style=“letter-spacing: normal”>kin<span style=“letter-spacing: normal”><span style=“letter-spacing: normal”>ds” which suggests “kin ds” - likely a rendering issue. Should be “all kinds of”.

**I found a way to do it here: Clear all direct Formatting EXCEPT Italics?
This seemed to work when I had tested it on another document.

I wonder whether all those issues are the result of working with small models or I had made unlucky choices or was doing something wrong?
Looking at how much time my current models already take on my laptop I hope I don’t need to switch to even larger, and thus (likely?) slower, models.

I am also trying out multiple instructions/starting prompts. I test them by copying a single scene into a new document, I hoped that would keep the model focused on its task instead of wasting time attempting to psychoanalyse me based on my author’s notes or something, and when it is finished copying over the changes/suggestions I think to keep.
However, as it is already getting late here it might be best if I talk about that another time.

I have also noticed an exception when that nemotron-3-nano-4b had attempted to edit a paragraph:


However, that happened ereyesterday. Maybe I should tomorrow check whether that still happens on the latest version.

Afterwards, I think I’ll download a Qwen model, if so many seem to like it. I’ll see how it compares with the others.

@WriterOfBadFanFics @KeithCu: PLEASE continue in YOURE own privat chat and stop spamming here! THANKS!