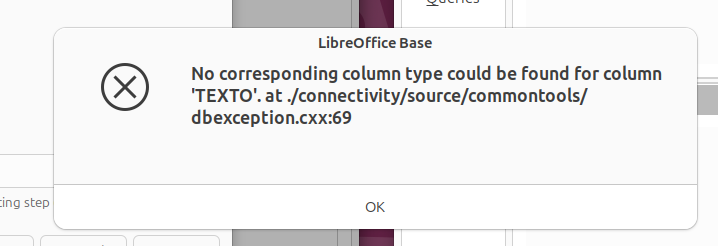
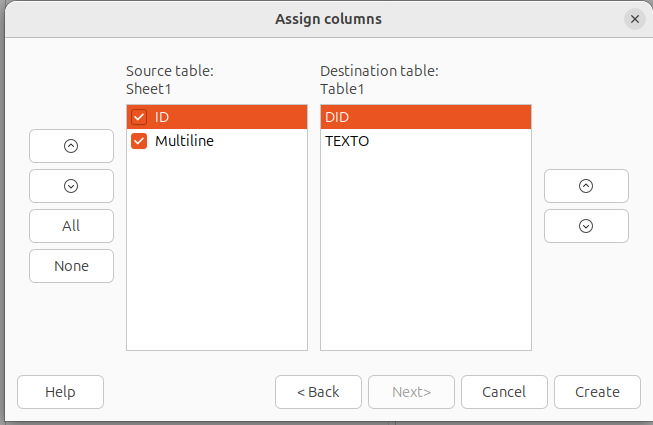
We have a language difficulty here that’s preventing me from fully understanding your responses. I’ve said several times that “connect” is not an option, and responses keep coming back “connect.”
“Connect” means “maintains a persistent link, and relies on the already-existing data source as the only copy, however it may be later edited (or not).” “Import” means “copies from the already-existing data source (which can then be forever disregarded) into an internal table.” I’m asking about “importing,” but responses keep coming back telling me to “connect.” I suspect this is a German-colloquial-use thing (and my data-processing-colloquial German is not up to task), but it might also be an actual incapability that appears inconsistent with the documentation. (There’s also a notation issue; I took the underscores like in “DB_HSQLDB.odb” to be parts of filenames or table names and not descriptions, because that’s what an underscore-instead-of-space means to me.)
There is one, and only one, .odb file at issue: The target Base file that should end up with all of the data from the multiple sources that have to be hand-massaged on the way in. The source material is currently in .xls files from which the data needs to be imported because once the import is complete, there will no longer be access to the .xls files. Thus, “import,” not “connect to” as any part of the process.
I’m going to try asking this an entirely different way. By using what I thought was an obvious simplified example, a bunch of tangents have derailed the thread.
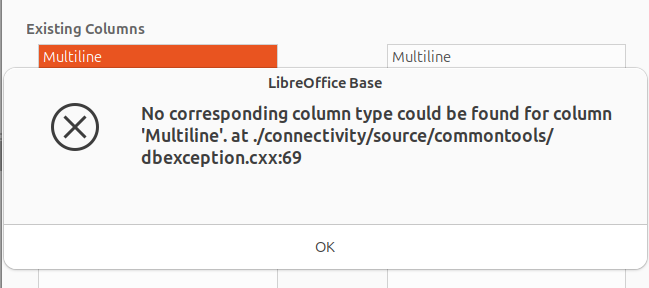
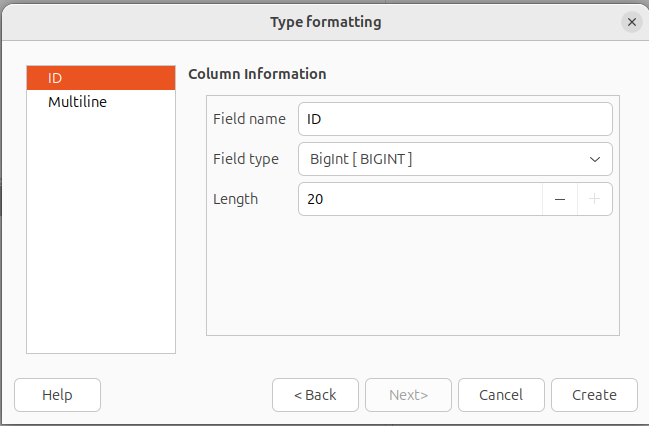
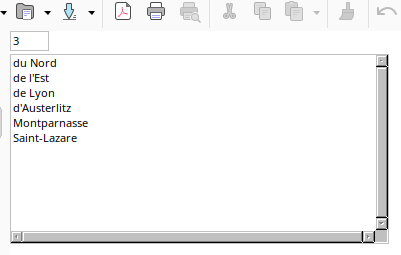
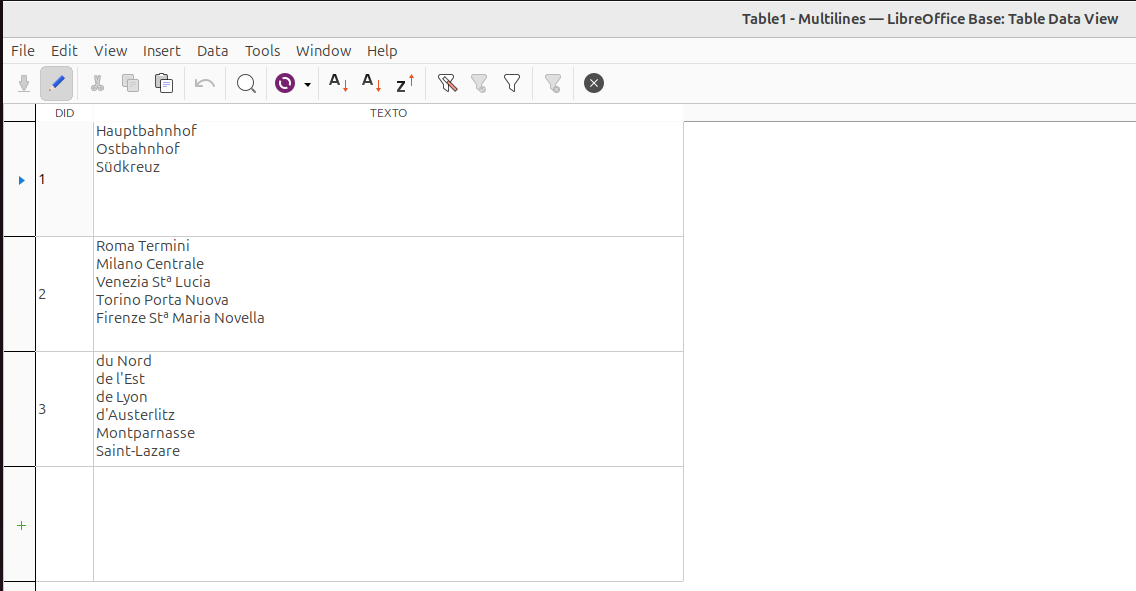
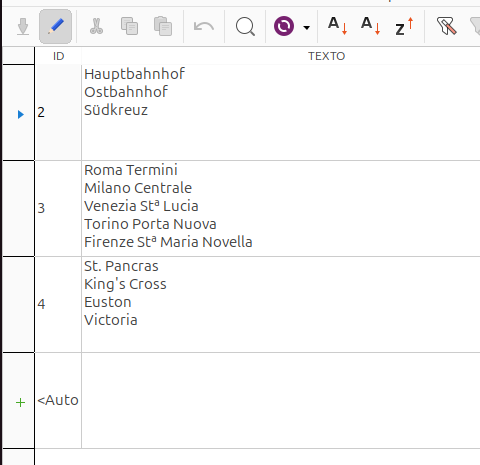
Consider a brand-new, completely unpopulated Base file in which one field in the only data table is designated as the “memo” type, and for each record that field is to contain a variable number of PARAGRAPHS that may be a single line or even more than 300 words (visualize “narrative on annual performance report” with linguistically separate paragraphs that are not data-processing-separate fields). The original data source, multiple .xls files, separates these PARAGRAPHS with line feeds ( ctrl-J on the keyboard ), but could be search-and-replaced to use any arbitrary character (like “@@@”) during the transfer process. The original data sources will NOT be available for later access: This ia a one-time import, and everything must end up inside a single table .odb file.
The “memo” field type appears from Base’s documentation and design to allow “multiparagraph” entries, and that’s what I’m trying to do with the imported data. The use of ctrl-J (which should translate directly to ASCII decimal 10, the line feed/LF character) works inside of Calc, Excel, and older spreadsheets… all of which blow up if they find ASCII decimal 13, the carriage return/CR character, inside of cells. Thus the present intermediate coding of LF only. The objective is to consolidate all of this data in a single location, at which point new records can be added and existing records edited without ever touching (or Base even knowing the existence of) the original data sources.
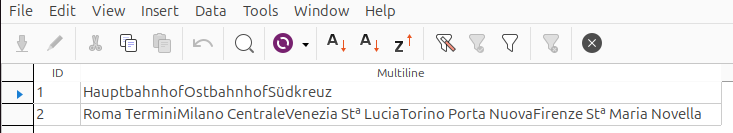
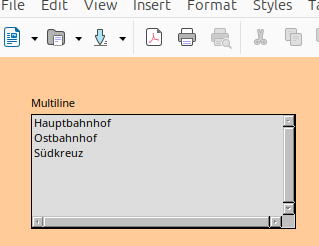
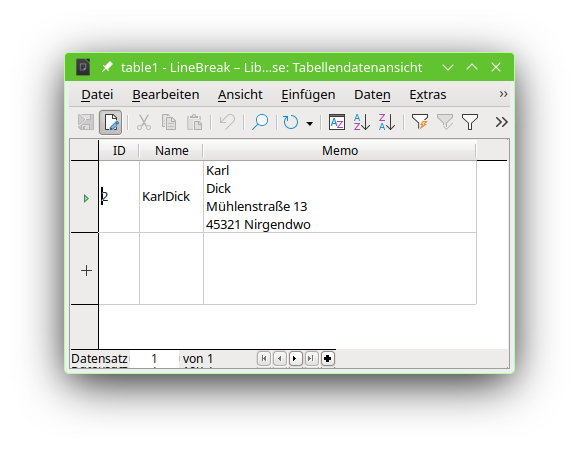
I’ve been unable to find a way in the current documentation and help system to take that imported data and reimpose paragraph breaks, in a memo-typed field, where there are supposed to be paragraph breaks — notwithstanding the apparent capability for the memo-typed field to contain multiple paragraphs. This would also apply to any other multiline input “cell” (individual record for that particular field), such as old-style addresses for non-modern postal systems, lists of ingredients or equipment, record-unique safety/verification checklists, and other non-separable-into-independent-field data; thus the initial question’s reference to “multiline.”